
LTX 2.5 — T2V & I2V ComfyUI Workflow (Free)
Frei
34 Personen haben dies gekauft
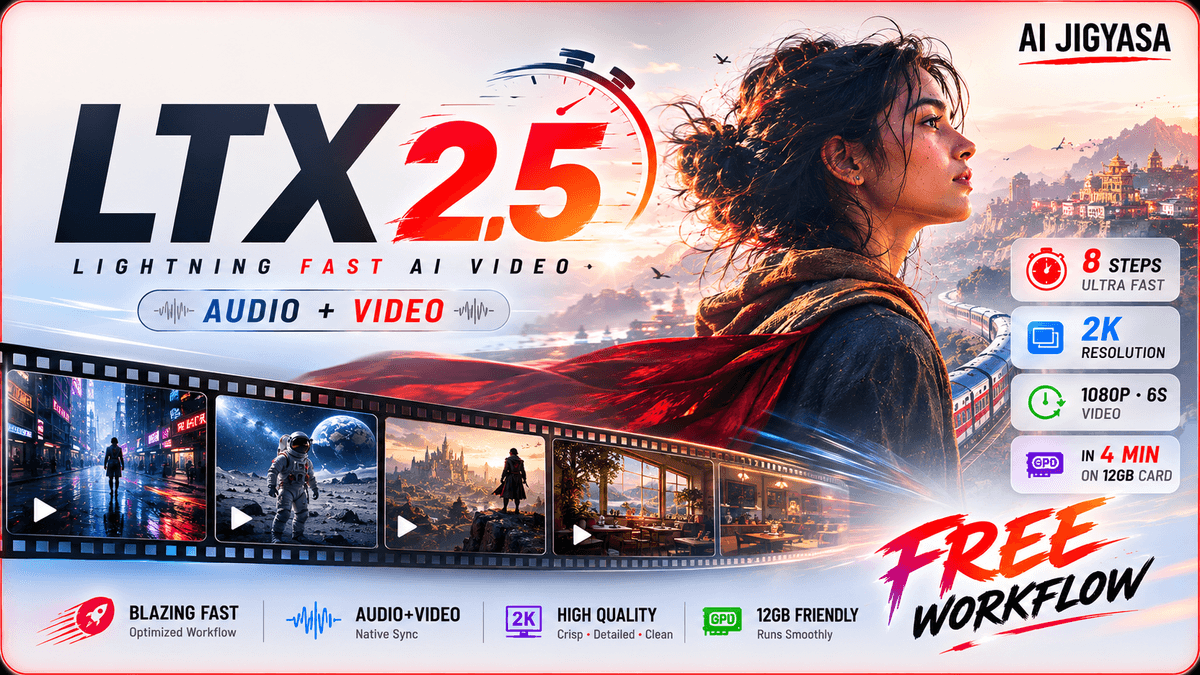
The fastest open-source video model just dropped — and this workflow gets you running it in ComfyUI in minutes. Text-to-Video and Image-to-Video in one clean setup, toggled by a single switch. No duplicate workflows. No re-wiring. Just flip and generate.
What's inside:
⚡ T2V + I2V Single Switch
One workflow handles both Text-to-Video and Image-to-Video via a bypass toggle on the LTXVImgToVideoInplace node. Switch modes instantly without touching anything else.
🚀 Built for Speed
LTX 2.5 is dramatically faster than LTX 2.3. The workflow uses the distilled transformer with torch_compile enabled and Multi-GPU patcher support — squeezing every bit of performance out of your hardware.
📐 Up to 2K Output
Native high-resolution generation with the built-in spatial upscaler. Width and height are controlled via clean primitive nodes — easy to adjust per shot without diving into the workflow.
⏱️ Duration Predictor Integration
The ltx-2.5-duration-head-bf16.safetensors model patch is wired in for auto duration prediction — the model figures out how long your video should be based on the prompt, so you're not guessing frame counts anymore.
🔊 Native Audio Generation
Full audio-video pipeline included — video VAE + audio VAE + audio decode all pre-wired. Your generations come out with synchronized audio from a single run.
🎛️ Manual Sigma Control
Advanced sigma adjustment nodes included for users who want to fine-tune motion quality beyond the default scheduler settings.
🧠 Gemma 4 Text Encoder
Powered by the new gemma4-12b-with-proj-ltx-2.5 text encoder — significantly better prompt understanding than previous LTX versions.
Model options covered:
Distilled BF16 — best quality
Distilled INT8 (ComfyUI-optimized) — best for VRAM-constrained setups
NVFP4 — fastest generation
Dev BF16 / Dev INT8 — for experimental use
All download links are in the YouTube video description.
What you need:
ComfyUI installed (latest nightly recommended)
LTX 2.5 models from Lightricks: https://huggingface.co/Lightricks/LTX-2.5
All model links in the YouTube video description
Who is this for:
Creators who want the fastest local video generation available right now
Anyone upgrading from LTX 2.3 who wants a clean starting workflow
ComfyUI users who want T2V and I2V without managing two separate workflows
Filmmakers who want native audio output without a separate pipeline
🎬 Watch the full tutorial on AI Jigyasa before loading the workflow — the video covers every model option, the T2V/I2V switch, prompt structuring.
💛 This workflow is free. If it saves you hours of setup and testing, a coffee keeps more open-source content like this coming.
Frei
34 Personen haben dies gekauft
Gib einen fairen Preis ein
$
Frei